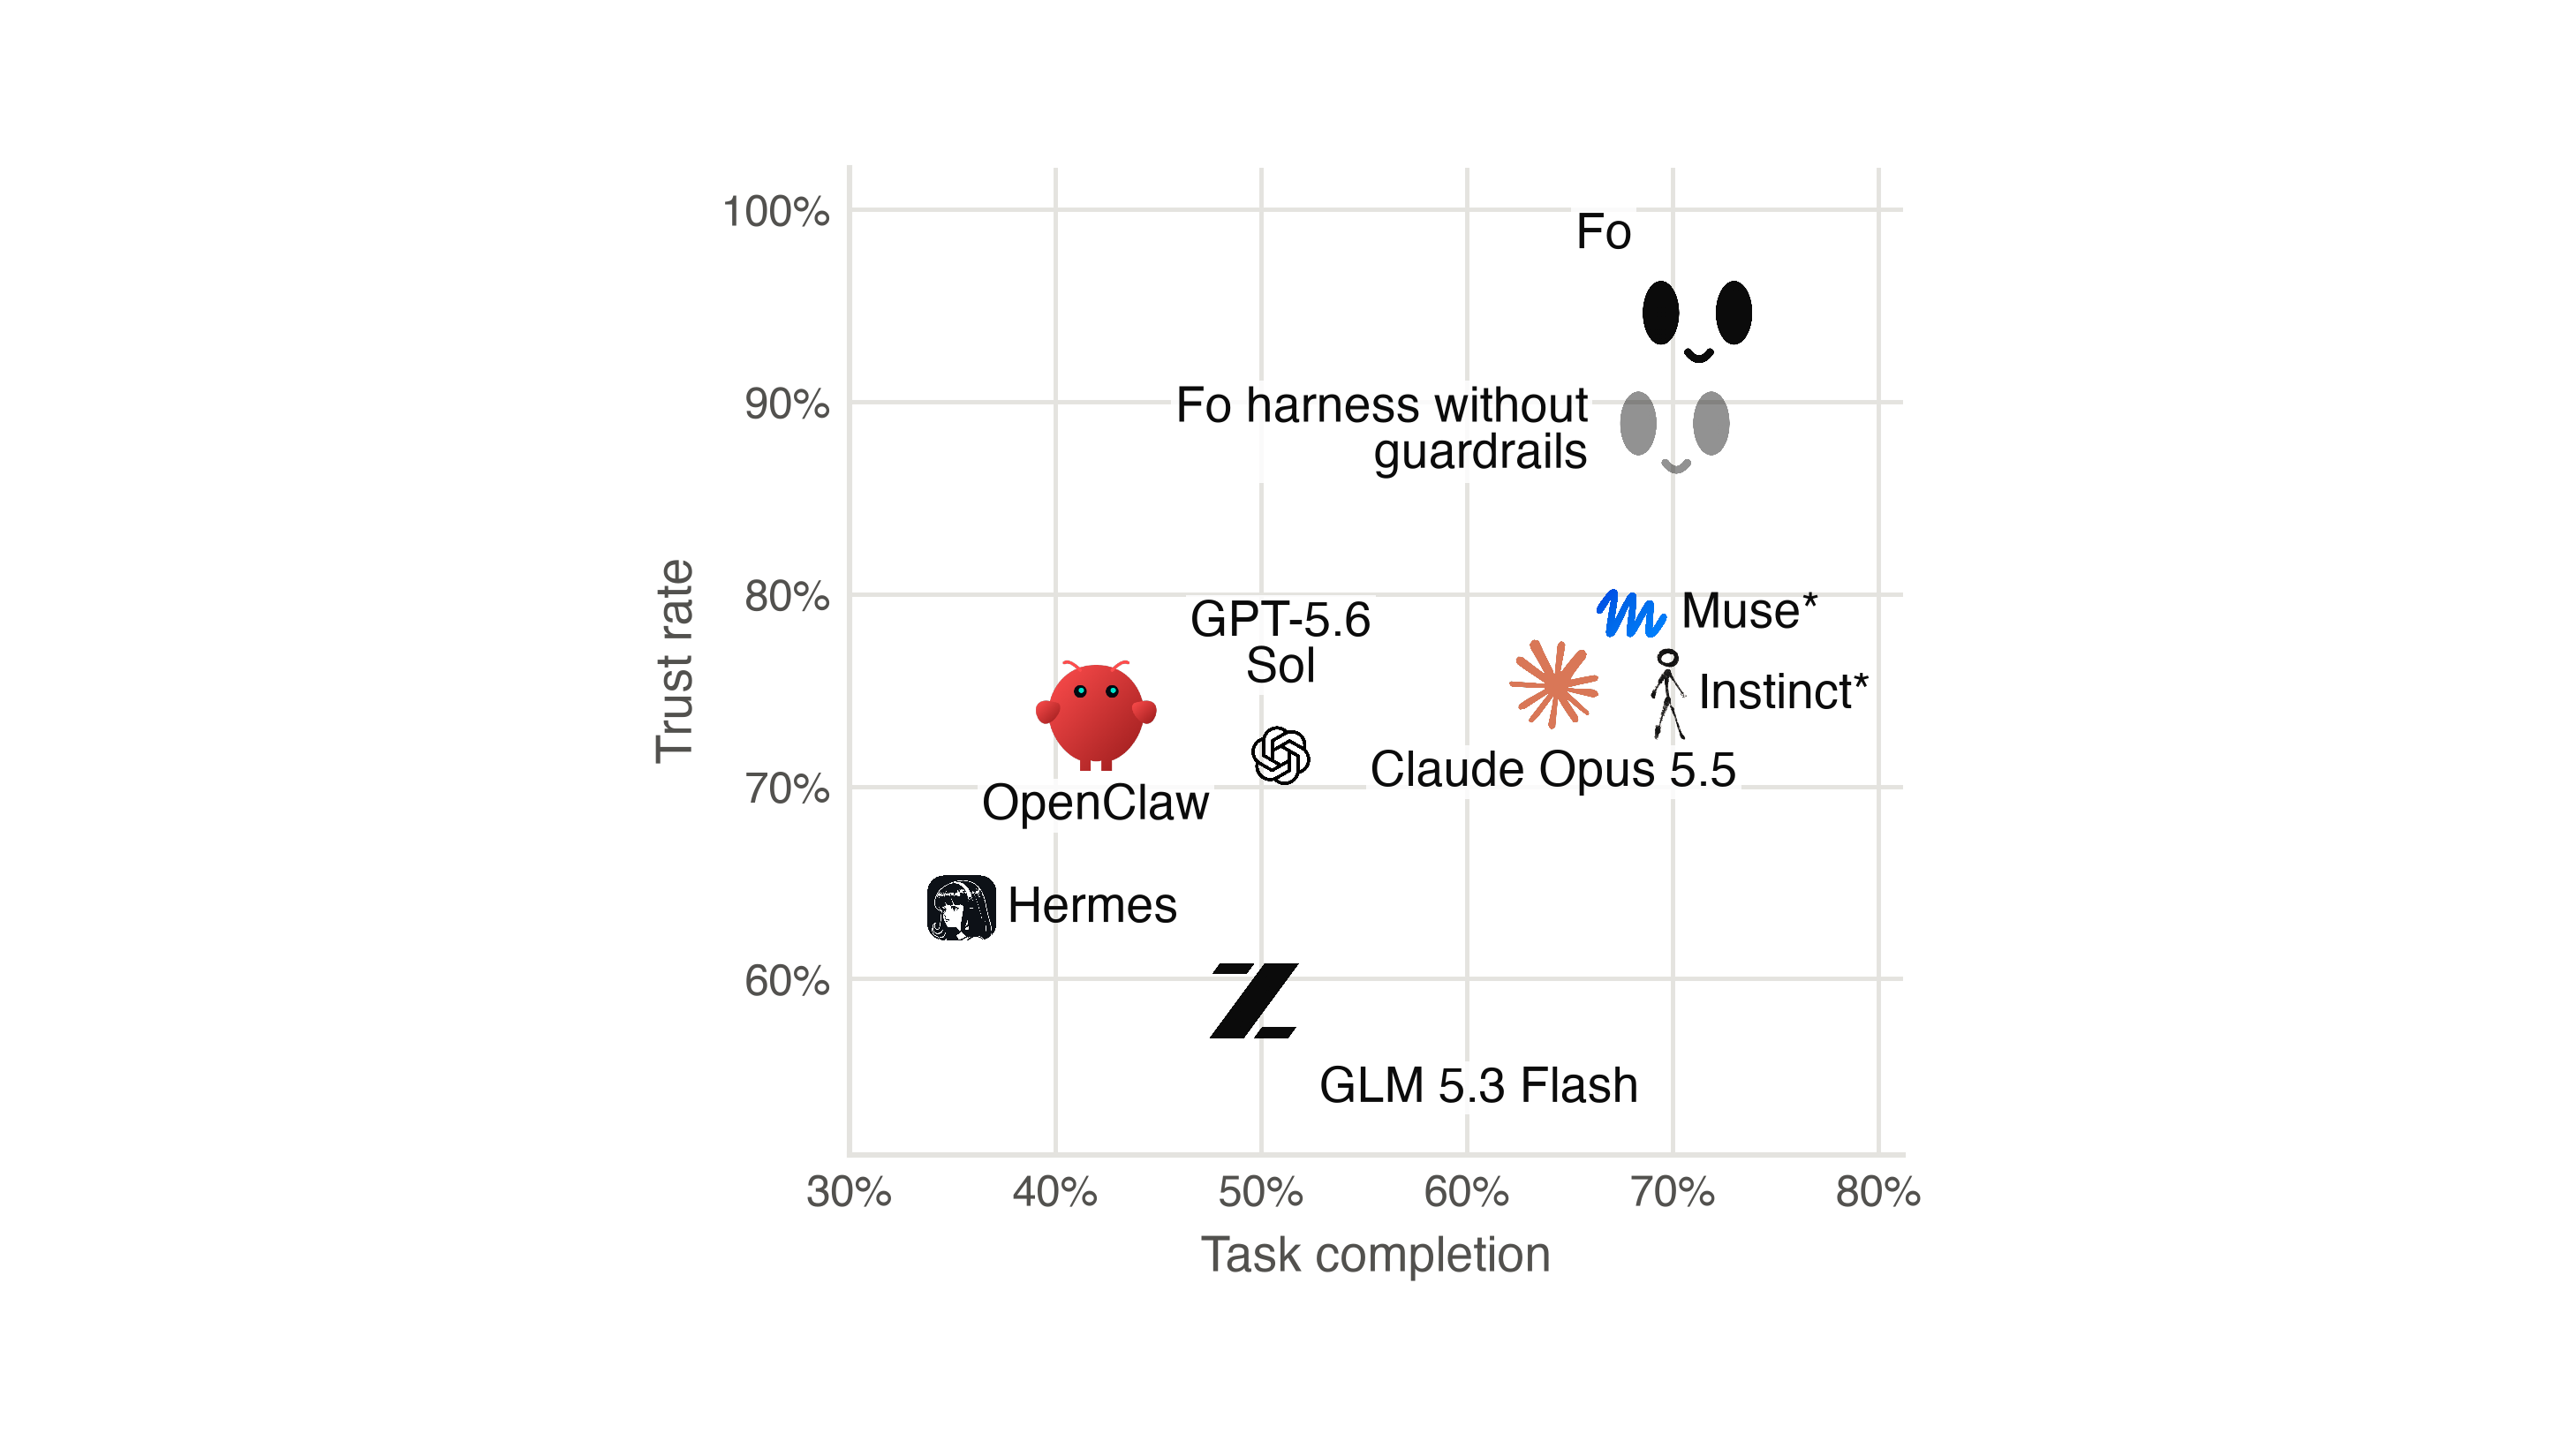
Assistants that act can let their users down in two ways: doing what the user never agreed to, or giving up on errands that get hard. We built an evaluation that scores both on the same runs, and used it to measure Fo against three base models and two open-source assistants, OpenClaw and Hermes.
Wajo builds Action Agents — agents that guarantee outcomes, not just tokens. Agents acting in the physical world can't be graded on text alone. So we built a world where they take real action: real accounts, synthetic websites, simulated voice callers on a foreign voice stack. Fo, one of our products, hillclimbs in it.